Open-source ML.
Ready to run.
Pick any model from the Hugging Face Hub. Download the app and run it. Detection, segmentation, VLMs, speech, diffusion, classification, depth, OCR, and more. Runs on CPU or GPU. Optional OpenAI-compatible API and MCP server. Nothing leaves your machine.
-
Florence-2-base462 MB
-
whisper-tiny150 MB
-
detr-resnet-50165 MB
-
segformer-b0-ade-51214 MB
-
Llama-3.2-1B-Instruct2.5 GB
-
InternVL2_5-1B↓ 1.9 GB
-
SmolLM3-3B↓ 6.0 GB
-
sam2.1-hiera-tiny↓ 150 MB
-
stable-diffusion-xl-base-1.0↓ 6.9 GB
-
bark-small↓ 1.2 GB
See it in action.
Three different models, three different tasks, all running locally on the same machine.
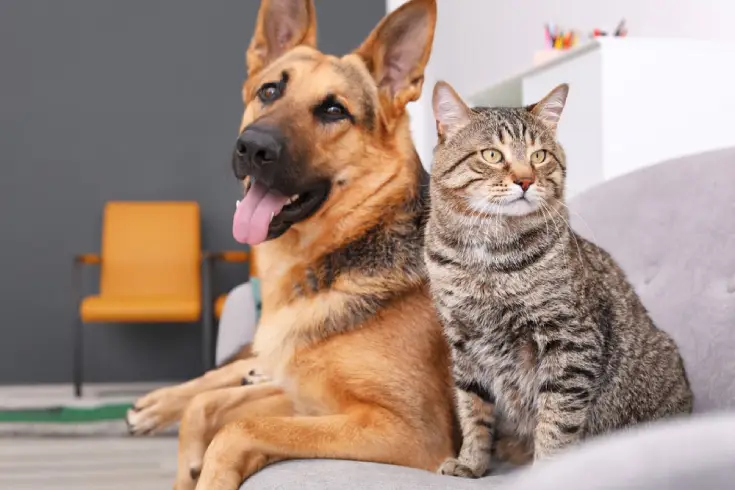
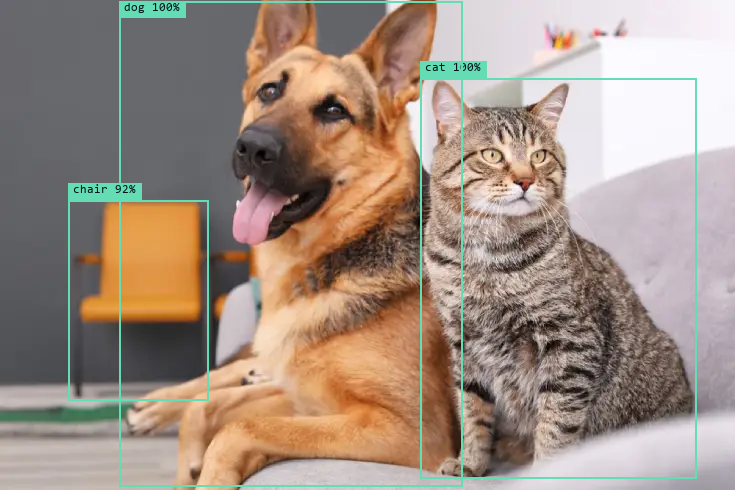
Find what’s in the frame.
Spot objects in a photo with DETR. Get bounding boxes, labels, and confidence scores, with inference running on your own machine.
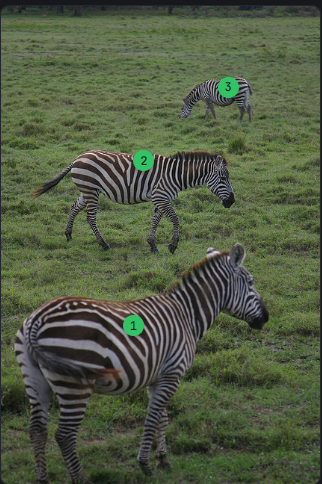
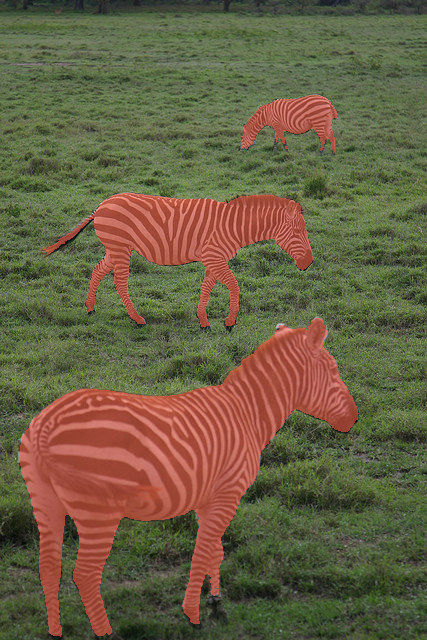
Go beyond the bounding box.
Select objects with point prompts and let SAM trace their outlines. Get per-pixel masks that separate your subjects from the background.
Give your words a voice.
Turn a text prompt into spoken audio with MMS-TTS. Play the generated speech right in the app, with inference running locally.
API and MCP Support
One switch in Settings turns your local models into an OpenAI endpoint - and into tools Claude can call. Off by default. Localhost only. It never serves the app's interface.
from openai import OpenAI

client = OpenAI(base_url="http://localhost:11500/v1", api_key="local")

resp = client.chat.completions.create(
    model="Qwen/Qwen2.5-0.5B-Instruct",
    messages=[{"role": "user", "content": "Hello!"}],
    stream=True,
)-
◇
Drop-in OpenAI SDK. Set base_url, use any api key. Nothing else changes.
-
◈
LangChain & LangGraph. ChatOpenAI(base_url=…) just works, so your agents run on local weights.
-
≋
Streaming. stream=True streams tokens over SSE, exactly like the hosted API.
-
⚙
Tool & function calling. Parsed per family - Qwen · Hermes · Llama · Mistral.
-
☰
Shares warm models. It runs inside the engine, so it reuses what the app already loaded - not a second copy.
Claude, with your models.
Register the MCP server once - the app copies the exact command for your install - and Claude can run anything ZeroInfer has installed. Eleven tools.
detect_objectssegment_imagegenerate_imagetranscribe_audiotext_to_speechgenerate_textembed_textsearch_modelsdownload_modellist_modelszeroinfer_statusNot just LLMs.
Eleven task workspaces. Every major modality.
Detection
DETR, YOLOS, RT-DETR, D-FINE, Table Transformer. Draws labeled boxes server-side.
Segmentation
SegFormer, Mask2Former, OneFormer, EoMT. Panoptic, instance, semantic. Composited overlays.
Mask generation
SAM v1, SAM 2, SAM 2.1, SAM 3. Auto grid-sampling mode, full multi-region output.
VLMs
Qwen-VL, LLaVA, Florence-2, Moondream, PaliGemma. Ask anything about an image.
Speech
Whisper, Wav2Vec2, MMS for ASR. SpeechT5, Bark, VITS for TTS. Both directions, long-audio aware.
Classification
ViT, ResNet, ConvNeXt, BEiT, SigLIP, CLIP. Image, zero-shot, audio. Confidence-ranked labels.
Diffusion
Stable Diffusion, SDXL, FLUX, Kandinsky, PixArt. Text-to-image, img2img, inpaint.
Text generation
Llama, Mistral, Qwen, Gemma, Phi, DeepSeek. Chat-template aware, reasoning-model aware.
Depth
DPT, MiDaS, ZoeDepth, Depth Anything v1/v2, Depth Pro. Single image → colorized depth map.
Documents · OCR
TrOCR, Donut, LayoutLMv3, Pix2Struct. Read scanned pages, receipts, forms. Ask questions about them.
Everything in the Hub, ready to run.
200+ model families, each one verified against our architecture whitelist. If it shows up in ZeroInfer, it loads. No broken downloads, no missing packages, no guesswork.
Detection
DETRYOLOSRT-DETRRT-DETRv2D-FINEConditional-DETRDeformable-DETRTable-TransformerOWL-ViTOWLv2Grounding-DINO
Segmentation
SegFormerMaskFormerMask2FormerOneFormerEoMTUperNetBEiTDPTDETR-panopticMobileViT
Mask generation
SAMSAM 2SAM 2.1SAM 3MedSAM
VLMs
Qwen-VLQwen2.5-VLQwen3-VLLLaVALLaVA-NextViP-LLaVAFlorence-2MoondreamPaliGemmaIdefics 2/3SmolVLMKosmos-2InternVLPixtralFastVLMLFM2-VLDeepSeek-VLJanus-ProFuyuOvisAriaGLM4VCohere2-VisionEmu3
Text generation
Llama 3/4GPT-OSSMistral 3Qwen 2/3Gemma 2/3/3nPhi 3/4DeepSeekSmolLM3OLMo 3OLMoEFalcon-H1Nemotron-HBitNetStarCoder 2CohereGraniteMiniMax
ASR · TTS
WhisperDistil-WhisperWav2Vec2MMSMoonshineParakeetSpeechT5BarkVITS
Diffusion
SD 1.5SD 2.1SDXLSD 3 / 3.5FLUX.1KandinskyPixArtSanaKolors
Classification
ViTDeiTSwinConvNeXtBEiTResNetEfficientNetMobileNetCLIPSigLIPSigLIP 2
Depth
DPTGLPNZoeDepthDepth AnythingDepth Anything v2Depth ProMiDaS
Documents · OCR
TrOCRDonutLayoutLMLayoutLMv2LayoutLMv3Pix2Struct